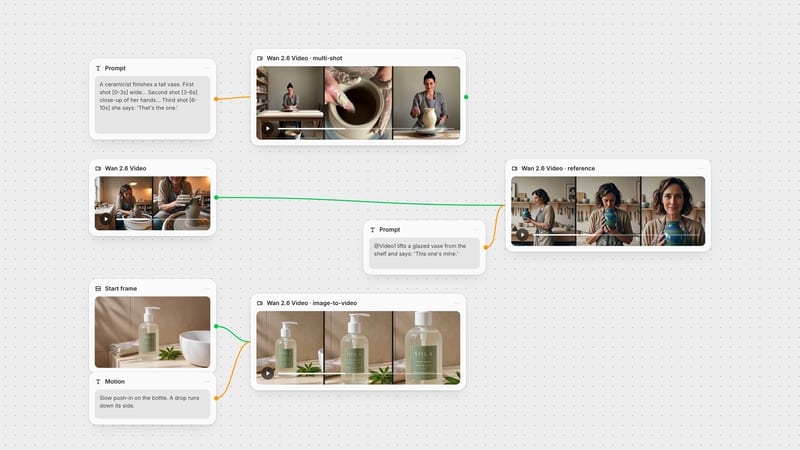
One click, whole workflow
Recipes are here. Package a whole workflow and run it in one click
Explore recipesOne click, whole workflow
Recipes are here. Package a whole workflow and run it in one click
Explore recipesbyAlibaba Cloud
Render cinematic digital art, intricate cultural motifs, and precise image-to-image transformations with bilingual prompt adherence
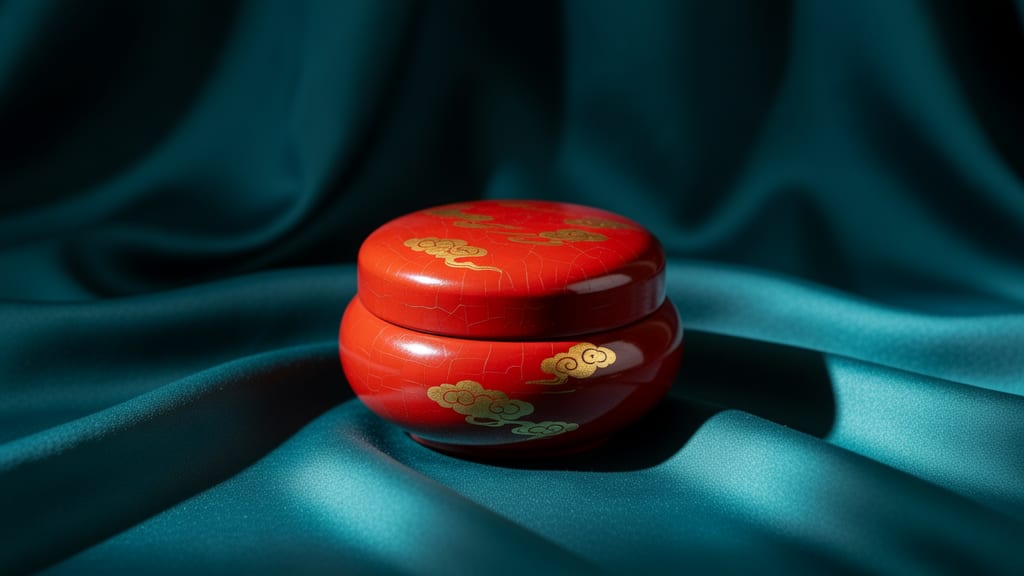
Craft rich prompt narratives or provide image references, pick your aspect ratio, and produce high-coherence digital visuals with precise composition.
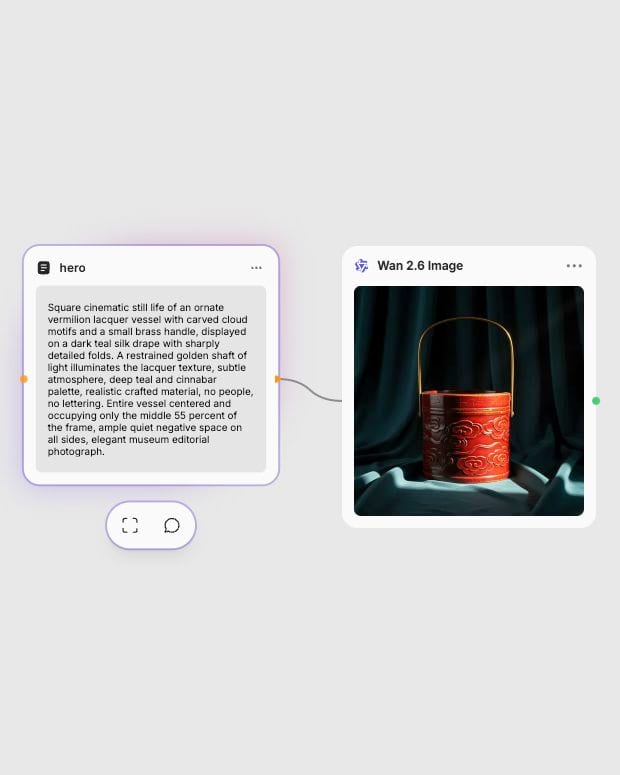
Describe your scene in detail
Write descriptive, multi-clause natural language prompts in English, Chinese, or both to steer composition and mood.
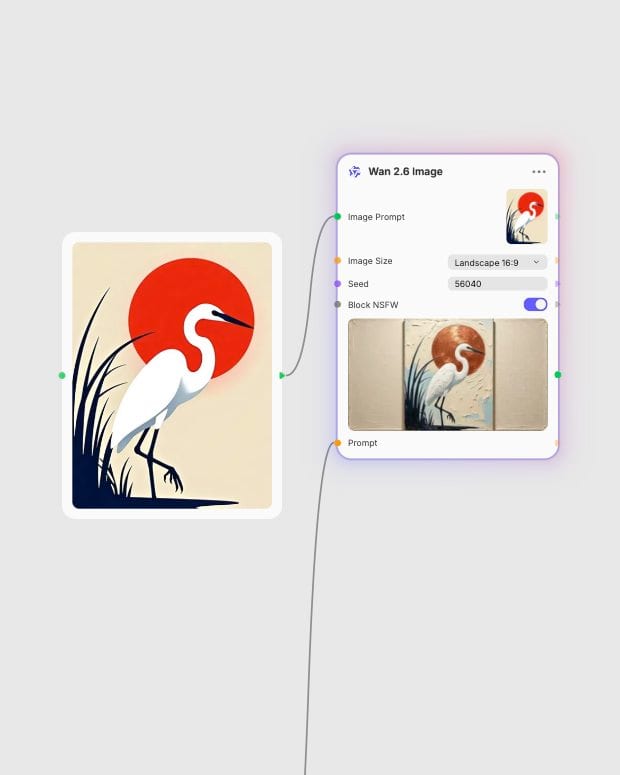
Add an optional reference image
Upload a flat high-contrast image to guide character identity, composition, or artistic style transfer.
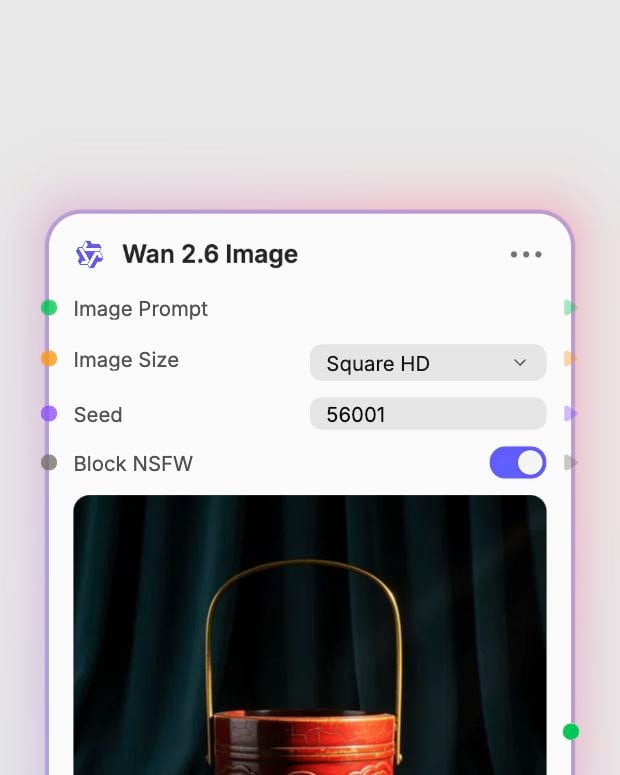
Select aspect ratio and render
Choose square, portrait, or widescreen framing to generate a balanced composition with cinematic lighting.
Built on a multimodal transformer architecture, Wan 2.6 blends deep bilingual comprehension, atmospheric light simulation, and flexible image-to-image style transfer.
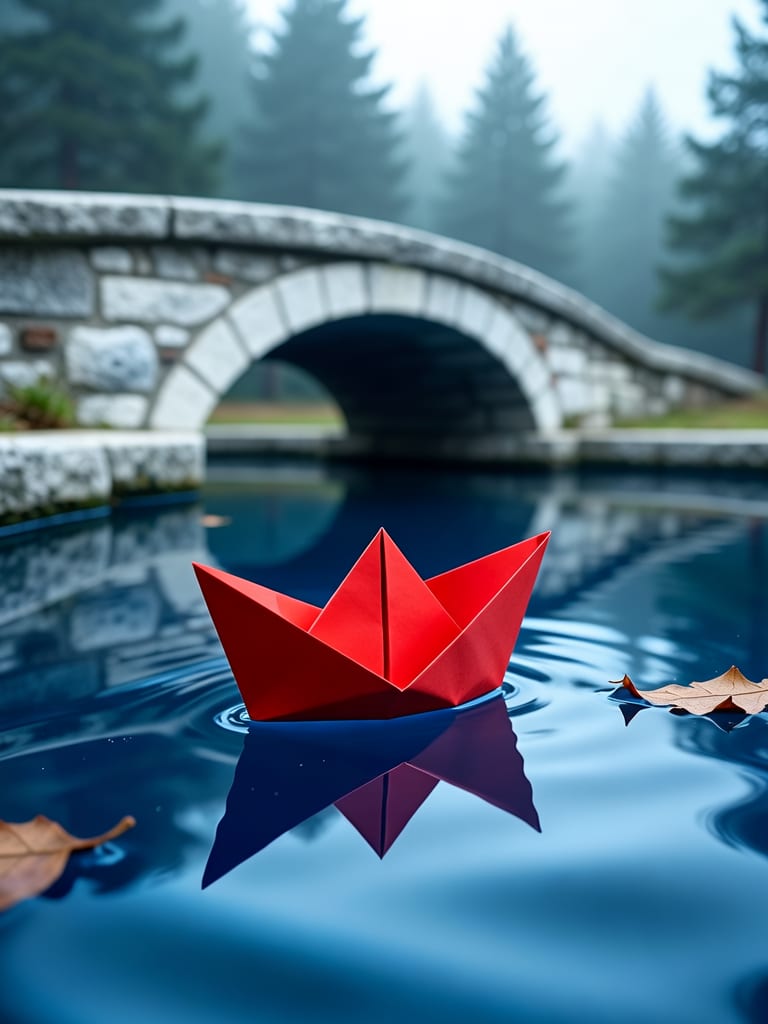
Bilingual Prompt Adherence
Powered by a UMT5-XXL text encoder, the model interprets complex narrative descriptions up to 2,000 characters across English and Chinese with accurate spatial layout mapping.
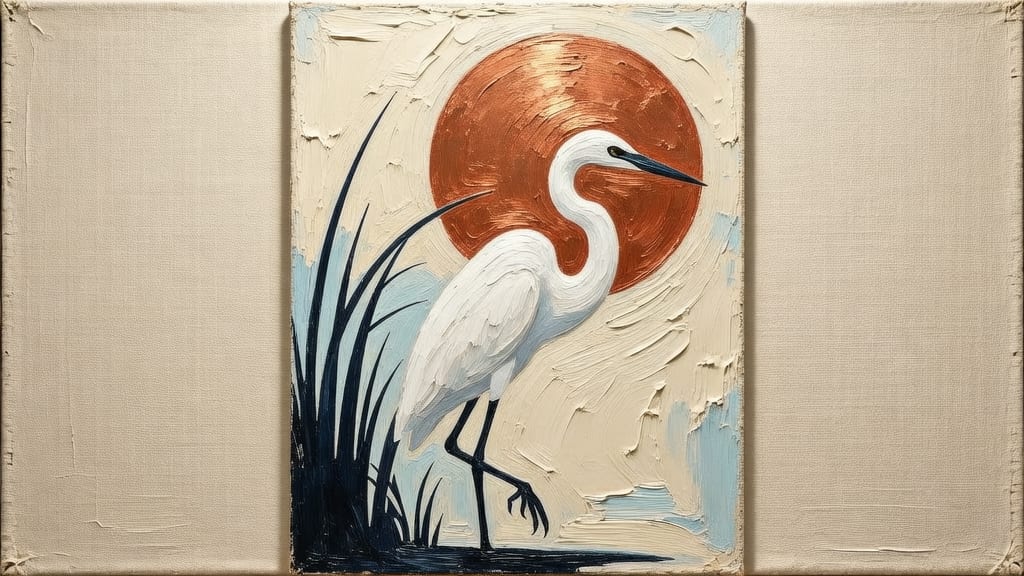
Structural Image-to-Image Transformation
Switch from text generation to the dedicated image-to-image pipeline to transform existing visuals, transferring painterly textures or cybernetic overlays while locking subject silhouette and pose.
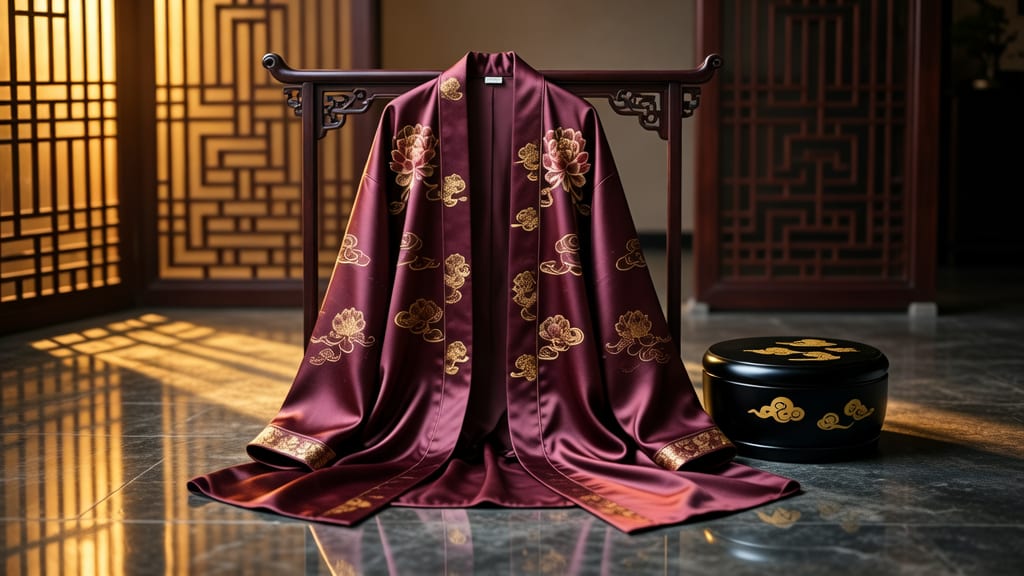
Cultural and Historical Fidelity
Render intricate East Asian architectural motifs, traditional silk garments, and lacquerware textures with authentic dimensional depth and clean line separation.
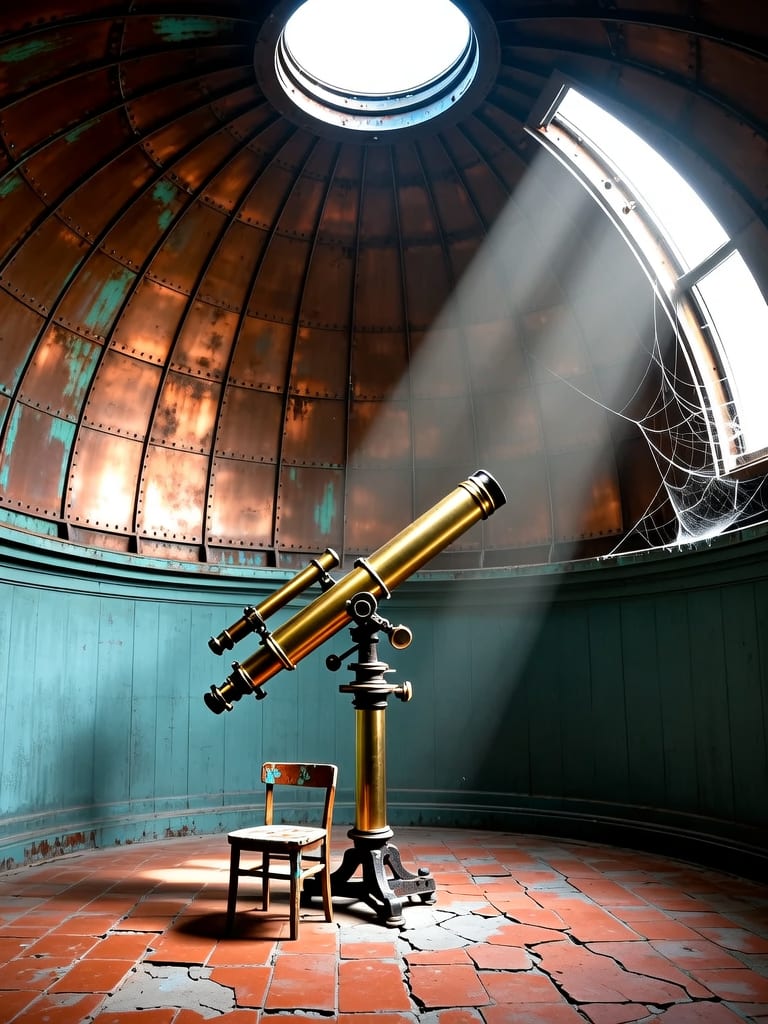
Cinematic Volumetric Lighting
The Multimodal Diffusion Transformer generates deep atmospheric perspective, casting realistic shadow falloff and directional light rays across complex multi-element scenes.
Explore a range of cinematic concept frames, tactile product renders, and stylized fashion editorials created across diverse visual styles.
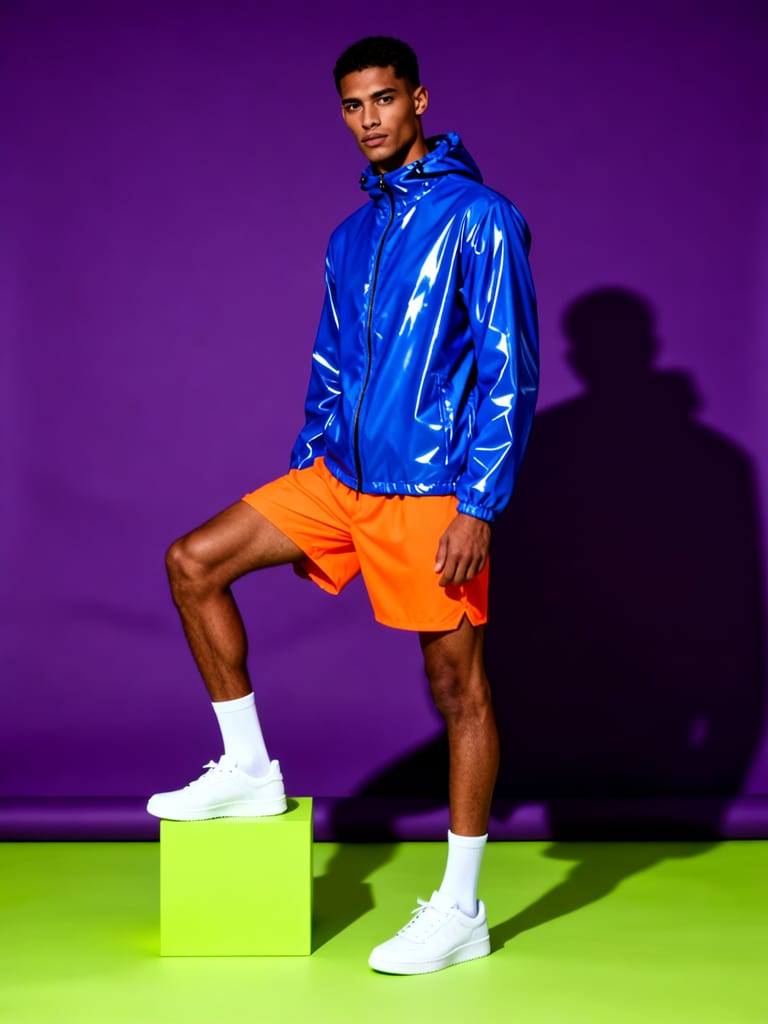
High-contrast sportswear lookbook with vivid color blocking
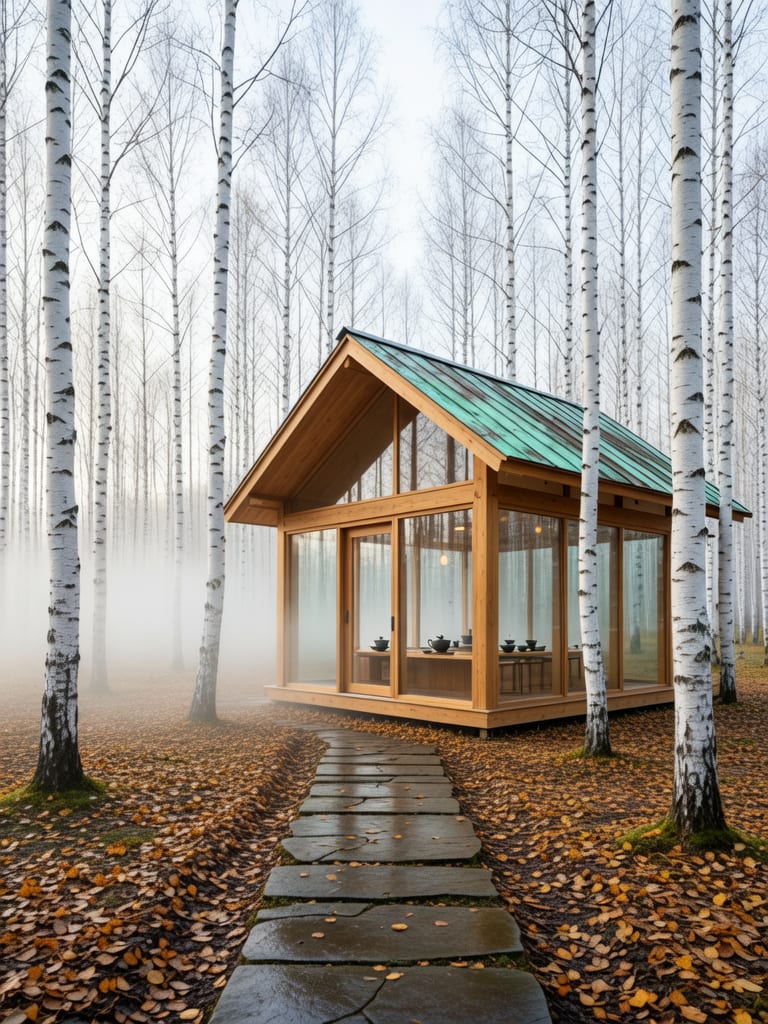
Architectural visualization of a contemporary timber tea house
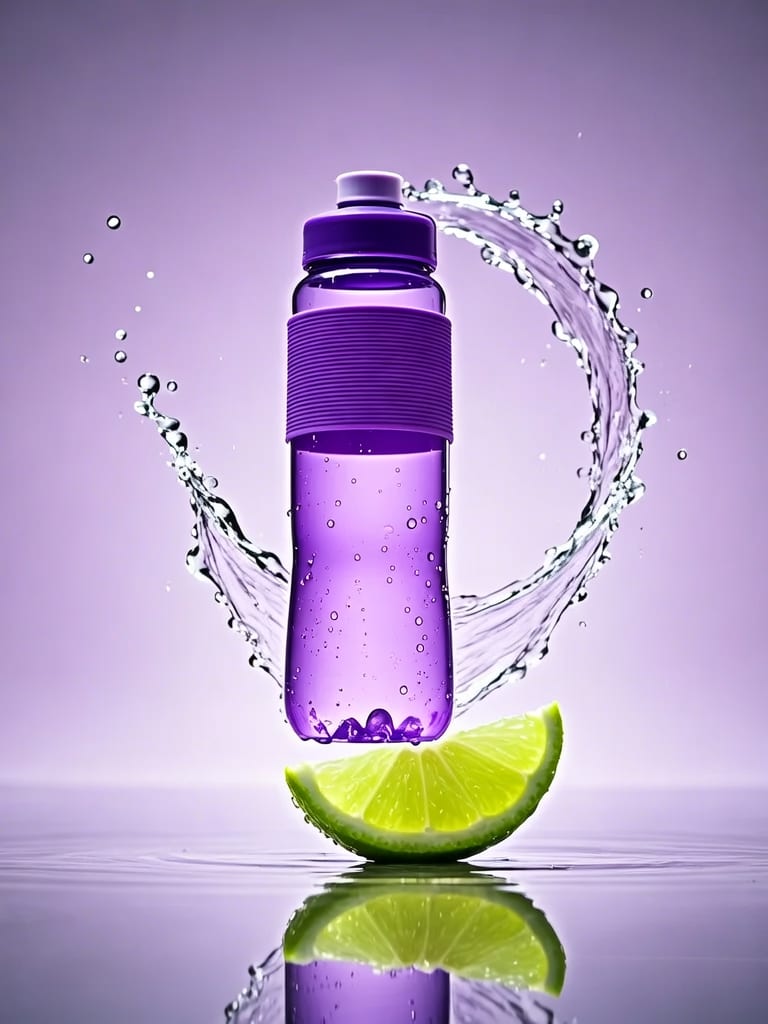
Commercial product campaign with frozen liquid motion
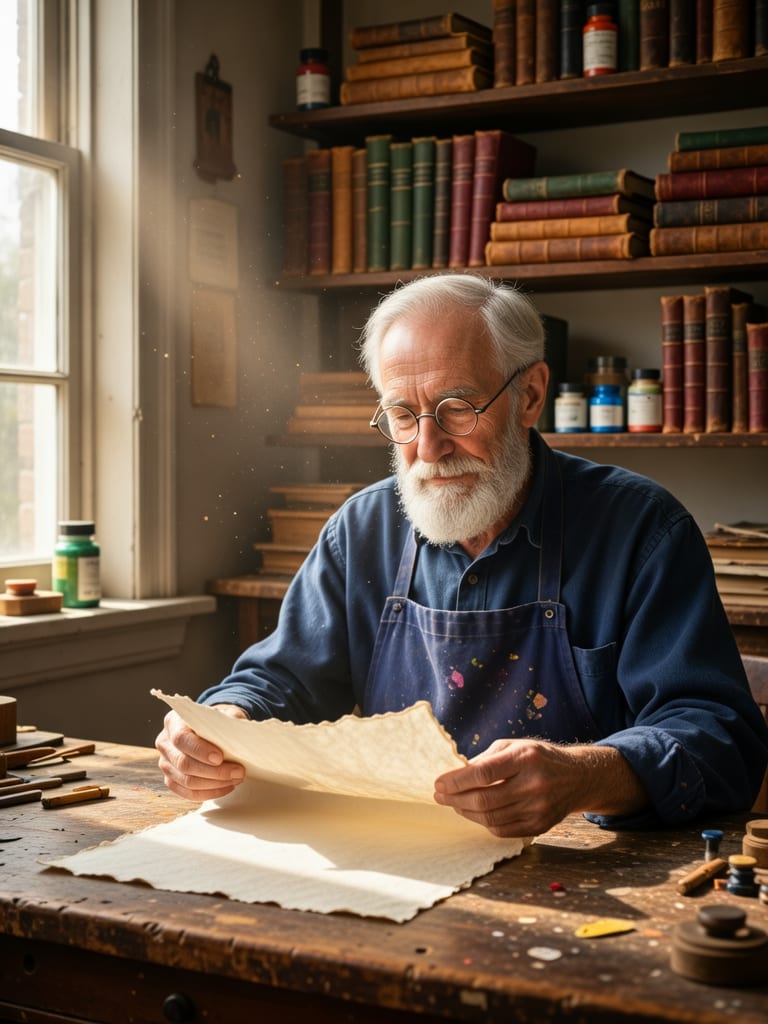
Editorial craftsmanship portrait with tactile material focus
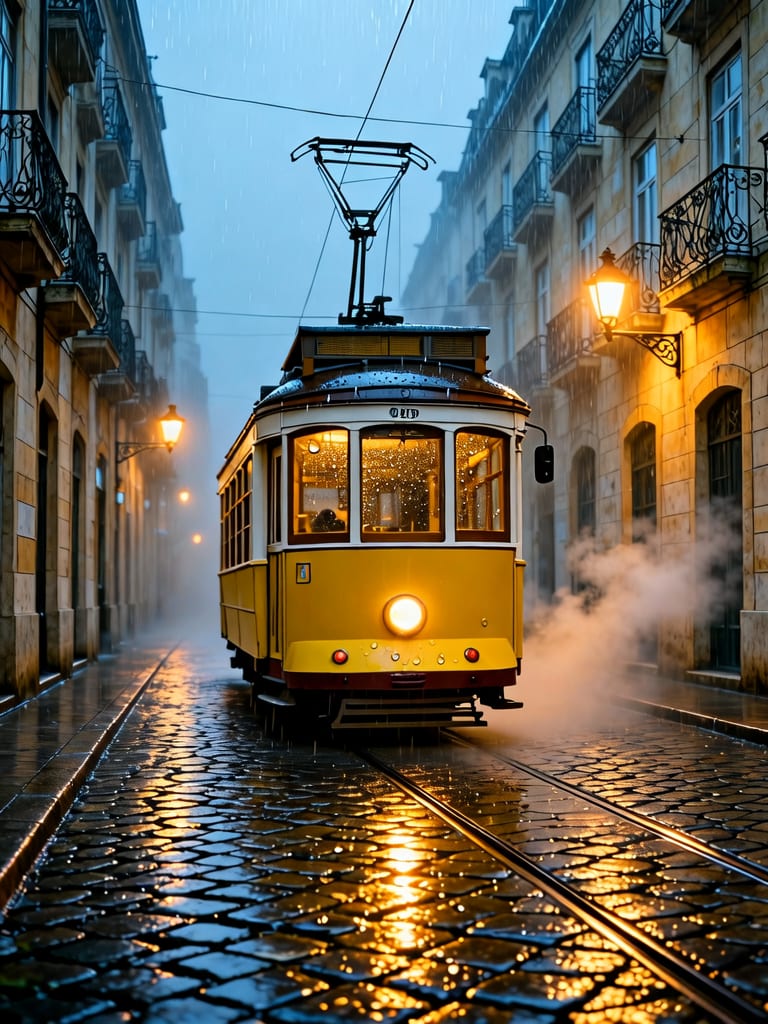
Cinematic transit frame with volumetric rain and reflection
From cinematic worldbuilders to fashion directors and product visualizers, discover how creators apply Wan 2.6 across creative workflows.
Text-to-image generates entirely new scenes from scratch using natural language prompts, while Image-to-image takes an existing reference image and applies aesthetic modifications or style transfers while preserving structural composition. Both modes support flexible aspect ratios up to a maximum resolution ceiling of 1280x1280 pixels.
Use Image-to-image when you need to maintain character silhouettes, apply fine-art textures to existing photography, or transfer color palettes onto established layouts. If you are ideating from a blank canvas without existing visual assets, Text-to-image is the ideal choice for rendering scenes directly from descriptive prompts.
Wan 2.6 excels at cinematic digital art, complex multi-clause storytelling descriptions, bilingual English and Chinese prompt adherence, and traditional East Asian cultural motifs. Its UMT5-XXL text encoder processes prompts up to 2,000 characters, producing scenes with high spatial fidelity and volumetric lighting.
Wan 2.6 is not optimized for organic analog film grain, vintage lens emulation, or flat minimalist vector icons. It also underperforms on ultra-sparse, single-word prompts because its text encoder requires descriptive phrasing to establish rich spatial context.
Wan 2.6 was developed by Alibaba Cloud and released in December 2025 as a multimodal diffusion transformer suite with a Mixture-of-Experts architecture.
Render cinematic digital art, intricate cultural motifs, and precise image-to-image transformations with bilingual prompt adherence