One click, whole workflow
Recipes are here. Package a whole workflow and run it in one click
Explore recipesOne click, whole workflow
Recipes are here. Package a whole workflow and run it in one click
Explore recipesbyStability AI
Turn descriptive text prompts into fluid, cinematic video loops with organic physics and sweeping camera motion in seconds
Generate short, high-fidelity motion clips from text prompts in three focused steps, from initial scene styling to fine-grained motion control.
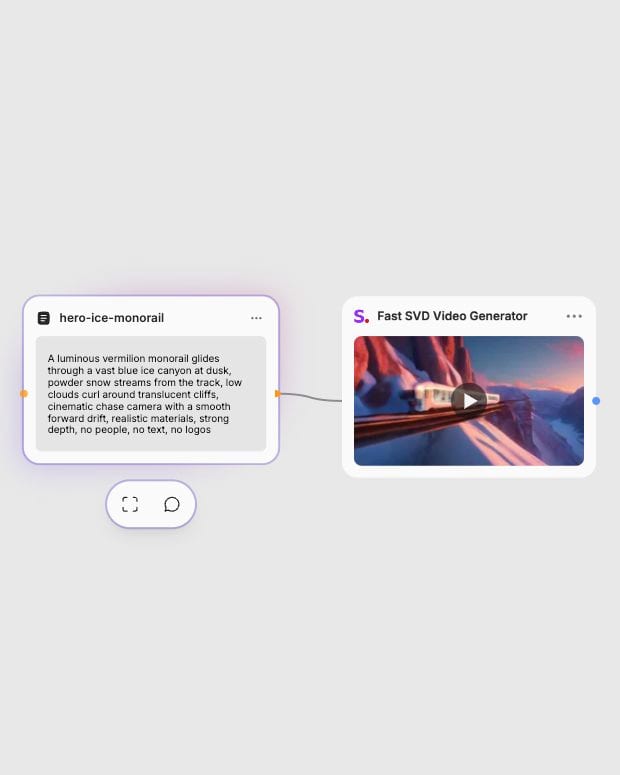
Draft your scene prompt
Describe the visual subject alongside natural motion cues like swirling mist, drifting embers, or slow camera pans.
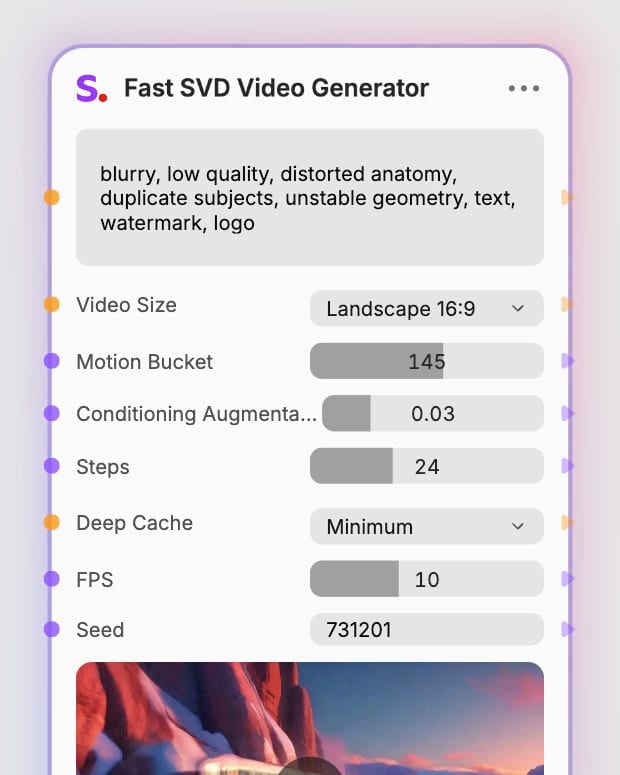
Tune motion dynamics
Set the motion bucket between 40 and 150 and configure DeepCache levels to balance rapid preview speeds with textural clarity.
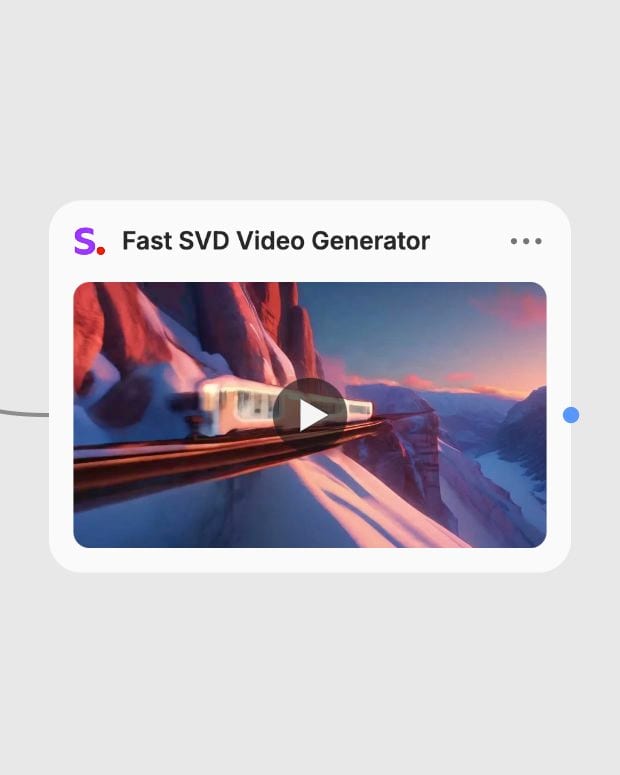
Generate 25-frame clip
Render an instant 25-frame cinematic clip ready for atmospheric looping, background plates, or storyboard pre-visualization.
Engineered for speed and temporal coherence, combining deep caching acceleration with granular velocity and camera tuning.
Explore high-contrast camera moves, organic fluid dynamics, and stylized motion tests rendered in 25-frame diffusion bursts.
From rapid commercial storyboards to ambient visual effects loops, discover how creators apply high-speed video diffusion across workflows.
Yes, Fast SVD Video Generator is built on Stability AI's Stable Video Diffusion (SVD 1.1) architecture, paired with an ultra-fast text-to-image front end and DeepCache acceleration. This setup translates text prompts directly into video latents and delivers completed 25-frame clips in under 15 seconds.
Fast SVD excels at subtle organic motion and cinematic camera sweeps, including flowing water, billowing smoke, hair moving in the wind, and smooth dolly or pan shots. It is specifically optimized for continuous, natural environmental dynamics rather than complex multi-stage human choreography.
The motion bucket ID controls the velocity and intensity of movement across the 25 frames, ranging from 1 to 255. Lower values (40 to 75) preserve structural anatomy and fine facial details, while higher values (100 to 150) produce pronounced camera motion and dramatic physical shifts.
DeepCache is an optimization method that skips redundant high-level U-Net calculations, speeding up rendering by up to 2x. Set it to 'none' or 'minimum' when preserving intricate facial textures and micro-details, or increase to 'medium' and 'high' for rapid landscape and visual effects pre-visualization.
Fast SVD is strictly limited to 25-frame generations (1 to 4 seconds of playback depending on chosen FPS) and cannot render legible text or complex multi-step human actions like walking or typing. Setting motion bucket or conditioning augmentation values too high can also cause anatomical warping or visual melting artifacts.
Turn descriptive text prompts into fluid, cinematic video loops with organic physics and sweeping camera motion in seconds