One click, whole workflow
Recipes are here. Package a whole workflow and run it in one click
Explore recipesOne click, whole workflow
Recipes are here. Package a whole workflow and run it in one click
Explore recipesbyAlibaba (Tongyi Lab)
Thirty-second single takes that hold a character's face and arrive with dialogue, foley and room tone already in the mix
You direct it like a shot: describe the moment, pin down references or start and end frames, choose a length up to 30 seconds, and get picture and sound back together.
Length, consistency and sound are the throughline: long takes without stitching, faces and products that stay put across references, and audio that arrives in the same pass.
The gallery runs from archival documentary and car commercials to a metronome visualizer, a color-clash lookbook and an underwater cave, all with sound generated in sync.
Directors, brand teams, social producers and music-video makers reach for it when one long, consistent, voiced shot beats a pile of short silent clips.
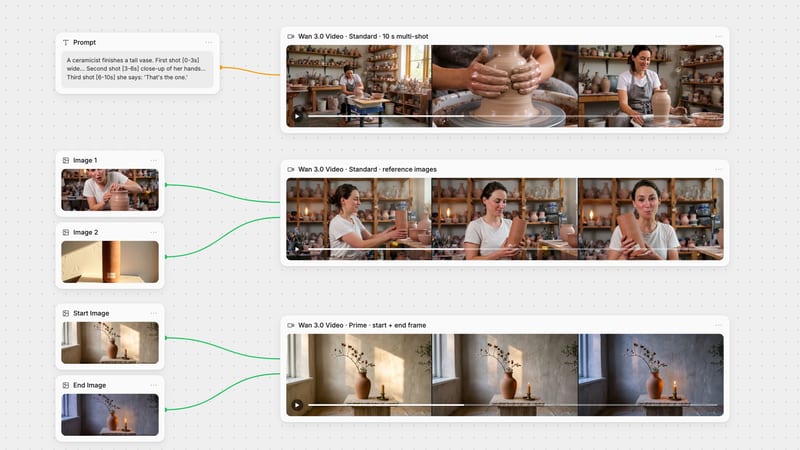
Prime is the faster tier for iteration, while Standard is the one to choose for finals where cost matters. They share the same capability set, so Prime does not add new features. It costs roughly 1.35x Standard, so draft timing and framing on Prime at 480p or 720p, then lock the final.
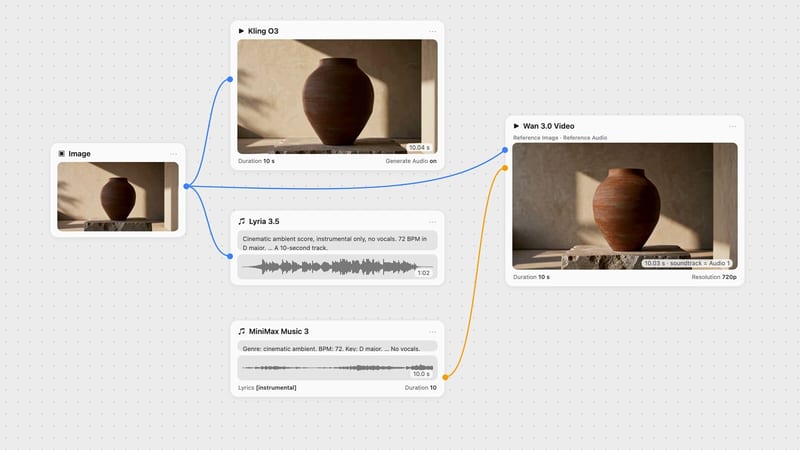
Match the variant to your anchor. Text-to-video suits concept exploration and establishing shots, but subjects can vary between runs. Image-to-video animates a designed first frame or bridges a start and end image, with the look locked to that frame. Reference-to-video keeps a character, product or location consistent using images, clips or voice audio, but needs careful numbering in the prompt.
Clips run from 2 to 30 seconds in one pass at 480p, 720p or 1080p, with 1080p as the default. If you use reference clips, their duration counts toward the 30-second budget alongside the output, so shorten the output when using long references.
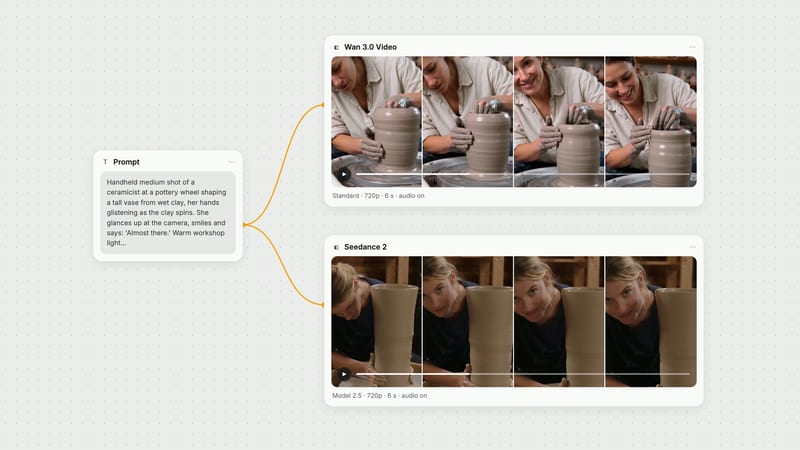
Yes, it generates synchronized audio such as dialogue, foley, ambience and music, and Generate Audio is on by default. Turn it off if you'll score the piece yourself. Put spoken lines in quotation marks for lip-synced voice, and say "no background music, no voice lines" to keep the sound quiet.
It struggles with fast action involving many interacting bodies, readable on-screen text, and crowded spatial scenes. Sparse prompts on 20 to 30 second takes can drift or idle, and 1080p at 30 seconds is costly for throwaway clips.
It comes from Alibaba's Tongyi Lab. Wan 3.0 is a closed, commercial model, so it isn't suited to local open-weight workflows.
Thirty-second single takes that hold a character's face and arrive with dialogue, foley and room tone already in the mix