One click, whole workflow
Recipes are here. Package a whole workflow and run it in one click
Explore recipesOne click, whole workflow
Recipes are here. Package a whole workflow and run it in one click
Explore recipesbyOpenAI
Transcribe multilingual speech with word-level precision or translate spoken audio directly into clean, punctuated English text
Convert raw audio files into clean, punctuated transcripts or English translations in three simple steps.
Upload audio recording
Provide a clear mono or stereo audio file under 25 MB in MP3, AAC, or WAV format.
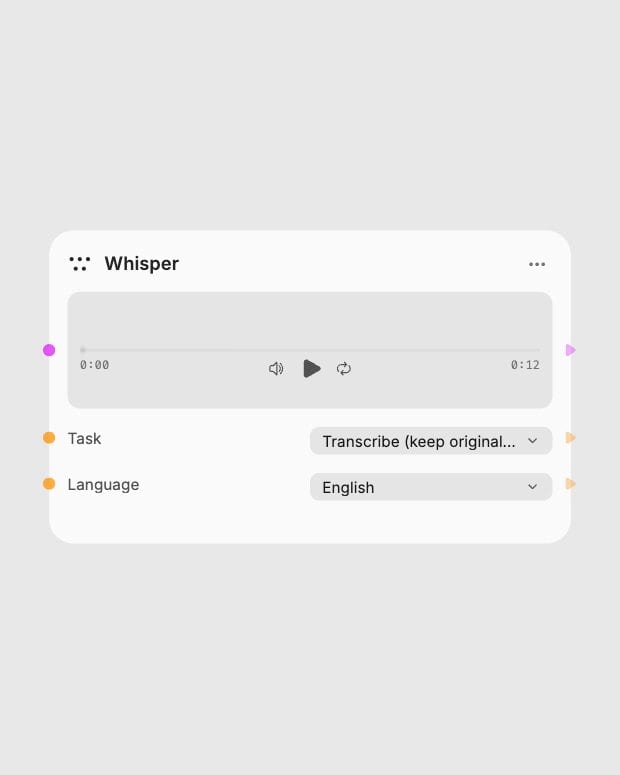
Select task and language
Choose whether to transcribe the original language or translate to English, with auto-detection across nearly 100 languages.
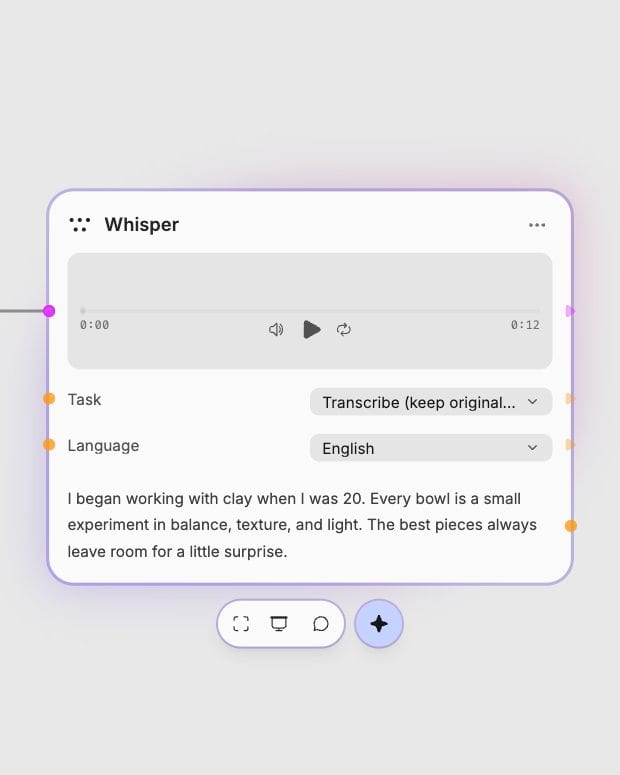
Receive punctuated transcript
Get clean, publication-ready text with standardized capitalization, punctuation, and normalized speech fillers.
Engineered on an optimized 1.55-billion parameter architecture for high-speed speech recognition across nearly 100 languages.
Explore real-world transcription and translation outputs across documentary audio, broadcast media, multi-speaker interviews, and video captions.
Built for video creators, documentary filmmakers, podcasters, and localization teams who need fast, verbatim-accurate speech-to-text.
Wizper is an ultra-optimized serverless implementation of OpenAI's Whisper v3 Large model. It delivers the exact same Word Error Rate (WER) and transcription accuracy as stock Whisper v3 Large (1.55 billion parameters) while running at more than double the inference speed at lower computational cost.
Audio files should be under 25 MB in standard formats such as MP3, AAC, or WAV. For optimal transcription accuracy, use clear mono recordings sampled at 16 kHz or higher, and pre-filter prolonged stretches of dead silence to prevent repetition loops.
No, the translation task is strictly unidirectional from foreign languages into English. The model can transcribe spoken speech in nearly 100 native languages, but its translation mode is designed solely to translate non-English speech directly into English text.
No, the model does not natively perform speaker diarization or label distinct speakers. It outputs all recognized speech into a continuous, punctuated transcript, so multi-speaker dialogue with heavy overlap may drop words if not separated beforehand.
Leaving the language setting on Auto-detect enables automatic language identification across nearly 100 languages. For audio clips shorter than 5 seconds or recordings with phonetically similar dialects, explicitly passing the language code eliminates detection latency and prevents misclassification.
Transcribe multilingual speech with word-level precision or translate spoken audio directly into clean, punctuated English text