One click, whole workflow
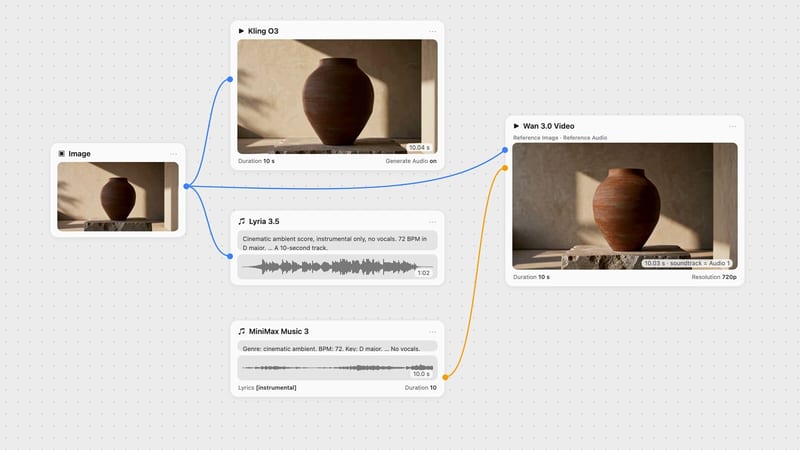
Recipes are here. Package a whole workflow and run it in one click
Explore recipesOne click, whole workflow
Recipes are here. Package a whole workflow and run it in one click
Explore recipesbyKuaishou (Kling AI)
Characters and products that hold their look through grounded, commercial-grade motion, with an optional end frame and synced sound
You direct a shot the way you would brief a crew: scene, subject, one camera move, then sound. Add frames to anchor the look, pick a tier and a length, and the model handles the motion.
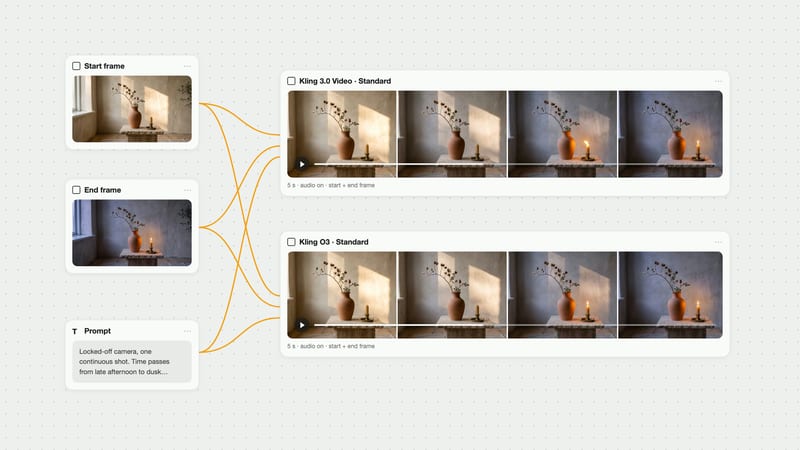
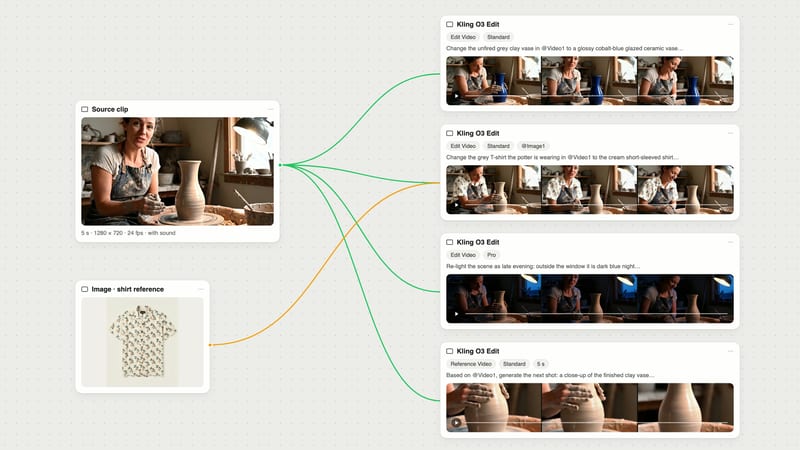
Each capability changes what a single shot gets: a cited reference that keeps a face intact, a second frame to travel toward, a finer render for the keeper, and foley and speech laid under the picture.
A gallery of single-subject shots covering fashion, product, film, hardware, and interiors, each with the grounded motion and matched sound the model produces.
The jobs covered here run from brand spots and product hero moves to vertical ads, scene previs, and lookbook runs, work for marketers, directors, social creators, and stylists.
Standard is the cheaper tier for exploring prompts, framing, timing, and audio cues; Pro is for final delivery, or when fine detail and consistency matter. Both are the same model at two quality levels. Pro costs roughly a third more than Standard across the 3 to 15 second range, so draft short on Standard first.
Match the variant to what you already have. Text-to-video suits scenes from a prompt alone, but it has no identity lock, so subjects vary between runs. Image-to-video animates an approved still, with an optional end frame. Reference-to-video holds a character, product, or look across the clip, and needs each image cited as @Image1, @Image2 and so on.
Each clip runs from 3 to 15 seconds in a single pass, in 16:9, 9:16, or 1:1. Use 3–5 seconds for one action and 10–15 seconds for a build with several beats. A one-beat prompt stretched to 15 seconds can drift or fill with filler motion.
Yes, turn on Generate Audio to get synchronized ambient sound, foley, and lip-synced speech. It is off by default. Cue the sounds in the prompt and put dialogue in quotes, saying who speaks and in what tone. Lip-sync can wobble on long or crowded lines.
It struggles with readable small text or labels, fine props in fast hand motion, and subtle facial acting, which tends to flatten into dramatic poses. It is also the wrong choice for clips longer than 15 seconds in one pass. With heavy reference sets, camera direction can occasionally reverse.
Kling O3 comes from Kuaishou (Kling AI) and was released in early February 2026. It is the Omni tier of the Kling 3.0 generation.
Characters and products that hold their look through grounded, commercial-grade motion, with an optional end frame and synced sound